
图生视频 AI
还是你的照片,只是动起来了。把静态图丢进 MaxH3,然后挑一个引擎——MiniMax H3、Wan 3.0、Seedance 2.5、Veo 3.1 等等都能读图,各有各对运动的理解。
用 MaxH3 的 AI 图生视频生成器让你的图片动起来
从你已有的照片开始,或者先生成 AI 图片再让它们动起来。然后告诉 AI 图生视频生成器要发生什么——一个神态、一次推镜、一整张分镜表——它会守住你给的那张脸、那套配色和那个构图。写实或插画风都行,带声音,一次出片。
原图
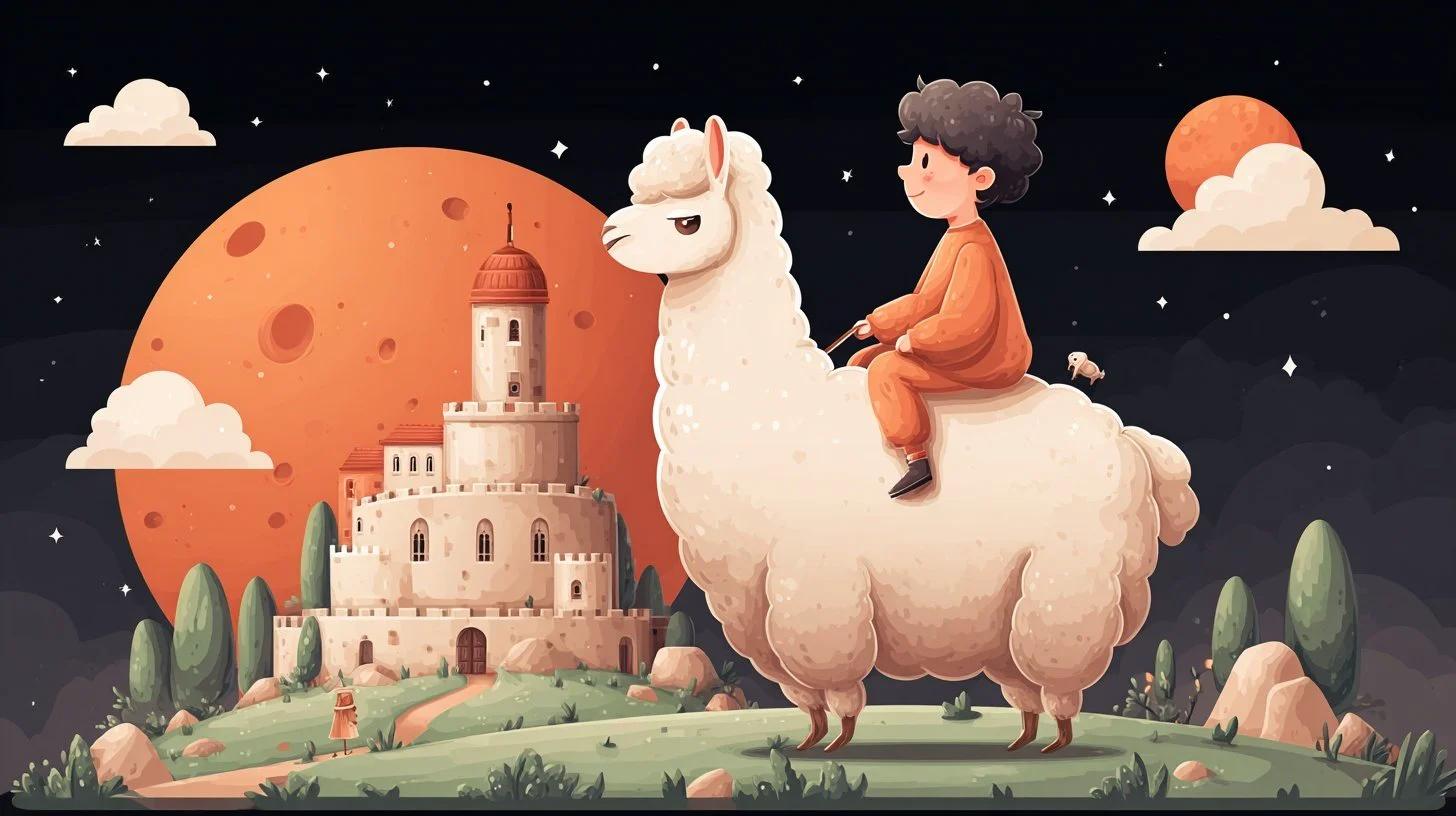
提示词
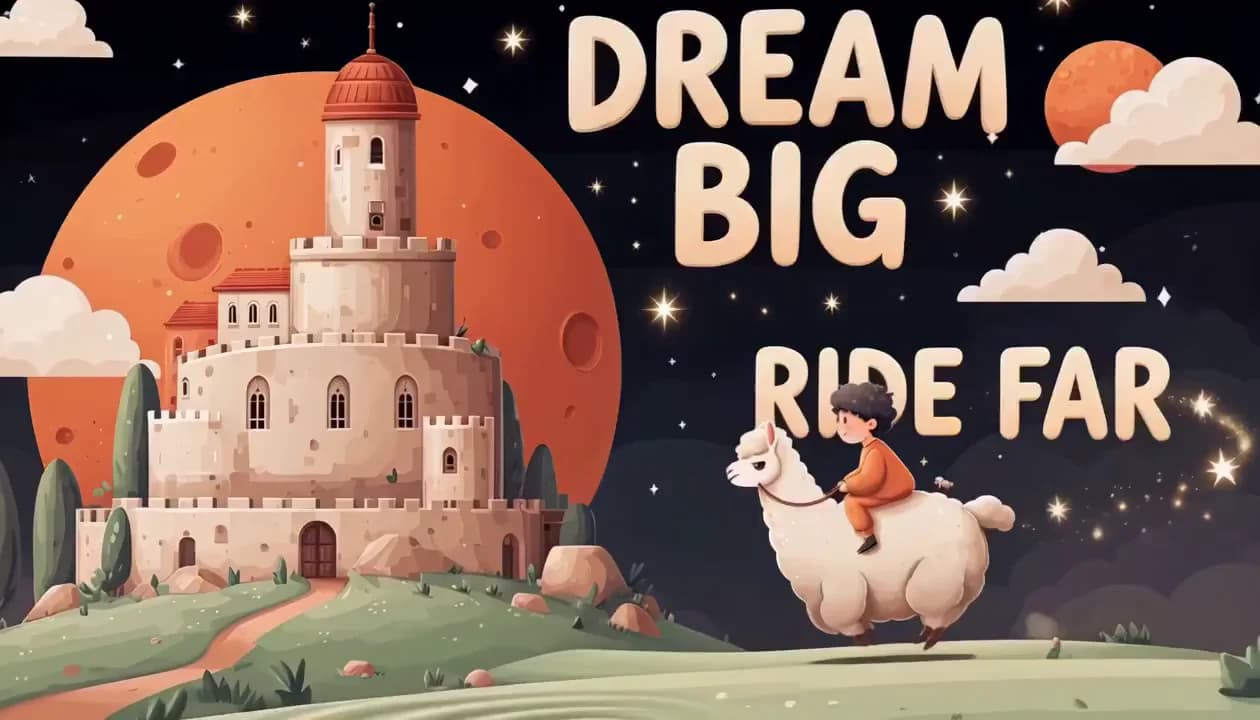
15-second, 16:9 whimsical illustrated fantasy motion-design film. Match the exact same visual style as the uploaded image: soft storybook/cartoon illustration, rounded shapes, gentle painterly shading, subtle texture, cute oversized proportions, dreamy atmosphere, coral-orange / cream / muted sage / deep midnight-blue palette, tiny stars, fluffy clouds, giant moon, magical castle. Never photorealistic. SUBJECT / MOTIFS A curly-haired boy in orange pajamas rides an enormous fluffy white llama through a moonlit fantasy landscape with a castle, giant coral moon, stars, clouds, rolling hills, and cypress-like trees. TEXT LEDGER — the only readable text: “DREAM BIG” “RIDE FAR” “TO THE MOON!” Typography: short, bold, catchy, rounded storybook lettering, clearly readable, warm ivory/coral tones. VISUAL CAUSALITY LAW Every motion must trigger the next one naturally: llama movement → ground ripple → castle reaction → moon reaction → stars/clouds → text formation. TIMESTAMPED CHOREOGRAPHY 00:00–00:01.5 Start on @[image1] exactly as shown, same composition and pose. Hold briefly. A star twinkles, the llama blinks, and the world gently comes alive. 00:01.5–00:04.0 The llama stamps one hoof. A ripple travels through the grass toward the castle. The castle towers pop upward playfully in sequence. A cloud breaks apart and reforms into the words: “DREAM BIG” 00:04.0–00:07.0 The llama begins a majestic, whimsical run toward screen right. The landscape slides in layered parallax. The boy leans forward happily, curls bouncing. A trail of stars curls behind them and forms: “RIDE FAR” 00:07.0–00:11.0 The ground bends like a springboard. The llama squashes, then launches into a huge leap across the giant coral moon. The moon's craters rotate and open like a magical portal. 00:11.0–00:13.8 Boy and llama burst through the moon surrounded by swirling stars and clouds. The stars spiral into large centered text: “TO THE MOON!” The boy lifts one arm triumphantly; the llama stays adorably unimpressed. 00:13.8–00:15.0 The text breaks back into stars. The stars, clouds, moon, castle, and landscape flow back into their original positions like a magical pop-up book resetting. End on @[image1] exactly as shown, matching the opening frame for a satisfying loop. FOLEY / AUDIO LAW Whimsical foley only: soft blink, hoof pomf, grass ripple wump, castle pop-pop-pop, cloud poof, gentle gallop thumps, sparkling star chimes, springy boing, moon portal whirr-whoom, final paper-like snap. No dialogue. TYPOGRAPHY MOTION LAW Text must emerge from the world: “DREAM BIG” from cloud pieces, “RIDE FAR” from star trail, “TO THE MOON!” from swirling constellations. CAMERA / DEPTH Begin as a still illustrated tableau matching @[image1]. Then use subtle multiplane parallax, a gentle push-in, and an upward tracking move during the leap. Keep the flat illustrated storybook feel, never realistic 3D. RHYTHM Stillness → awakening → playful motion → moon leap → magical payoff → return to start. FAILURE CONTROLS Maintain the exact look and charm of the reference image. Keep the boy small and orange-clad, the llama huge and fluffy white, the moon coral-orange, the castle cream-colored, and the world dreamy and cute. No photorealism, no extra characters, no off-style design, no unreadable text, no random objects, no uncontrolled morphing.
输出视频
原图
提示词
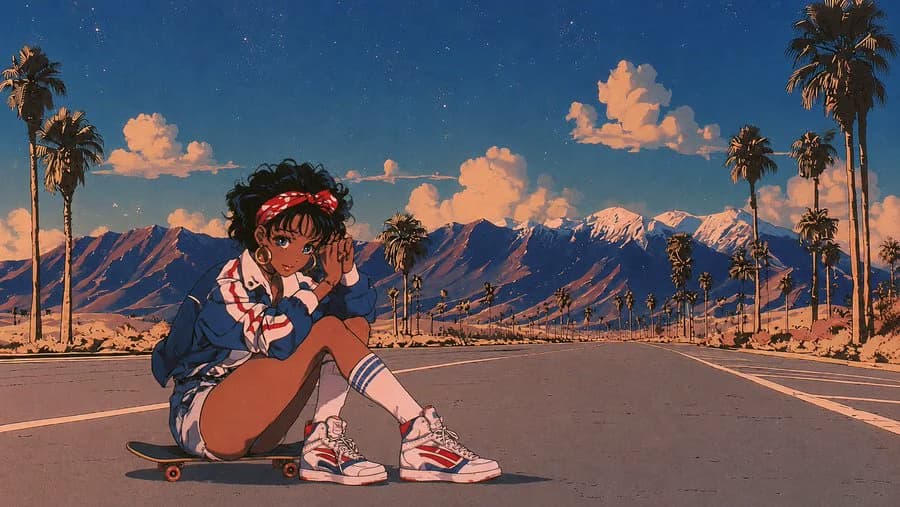
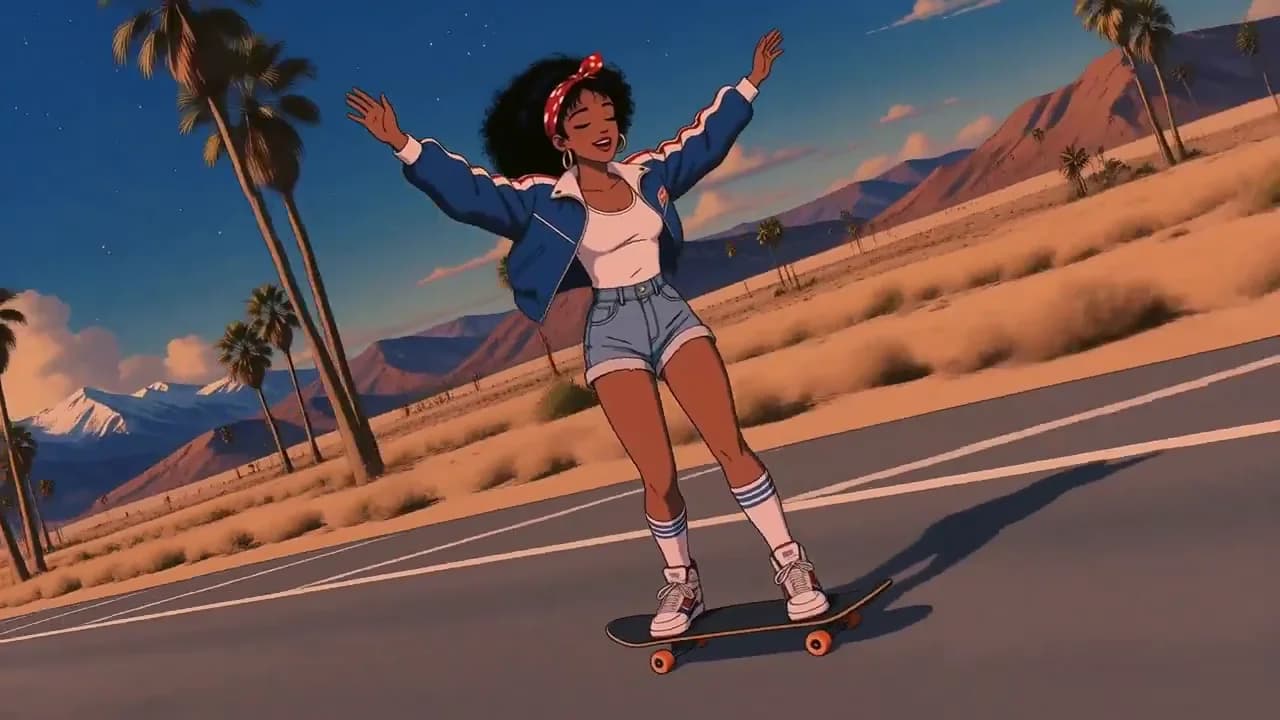
A cinematic 1980s-inspired music video sequence of a woman skateboarding through Death Valley at golden hour. She feels free, joyful, and fully in the moment, moving in the rhythm. [cut] Wide front shot. She skateboards down the open Death Valley road. She moves to the rhythm, enjoying the moment, gliding smoothly with relaxed energy. She lifts her hands high in the air. Wind blows through her hair. Camera tracks backward in a wide front shot. Vast road, desert plains, and distant mountains behind her. [cut] Medium close-up. She keeps skateboarding and starts singing: "Now here you go again you say...". Her mouth is clearly visible. She closes her eyes for a moment, hands still raised, smiling softly and enjoying the moment. Wind moves through her hair. Keep the framing intimate and expressive. [cut] The camera begins a smooth rotation around her as she continues singing: "you want your freedom..." and transitions into a side shot. She keeps skating with relaxed, rhythmic movement. She closes her eyes briefly again, still enjoying the moment. Side angle shows her gliding smoothly with the open road and desert landscape beside her. [cut] The camera continues spinning into a back shot, showing her hands lifted as she skateboards forward through the empty desert road. She keeps enjoying the moment as the camera continues its fluid rotation toward the opposite side. While the camera reaches the side shot again, she sings: "Well who am I to keep you down?" and lowers into a crouched skateboard pose, riding close to the board with bent knees, balanced and playful. She smiles, hair blowing in the wind, still fully in the moment. [cut] Aerial closing shot. She lifts back up from crouched skateboard pose to standing skateboarding, moving into the rhythm as the camera lifts above her and slowly spins around as she continues skateboarding down the long Death Valley road. Reveal the open road, desert plains, and distant mountains all around her. End with a wide cinematic feeling of freedom and space.
输出视频
原图
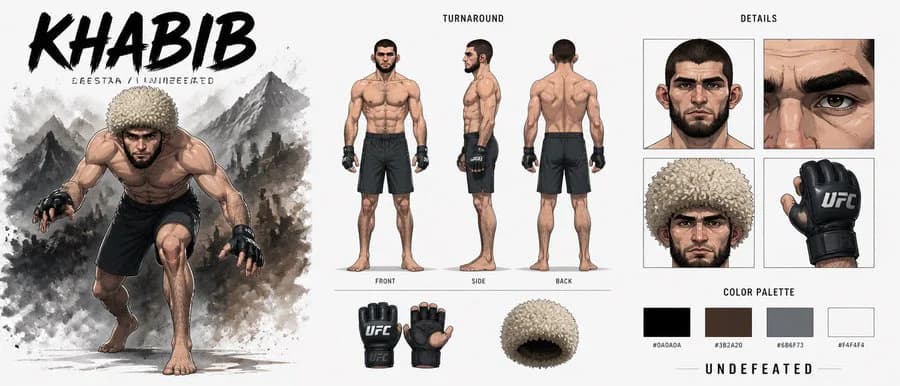
提示词
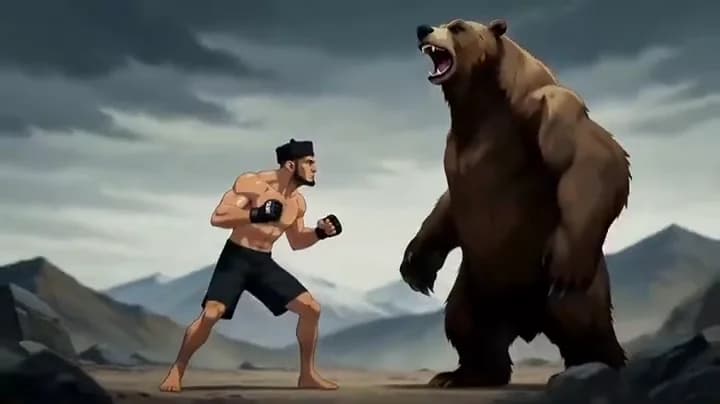
Cinematic anime short film clip, 15 seconds. Wild Dagestan mountain landscape, rocky terrain, grey cloudy sky, snow on distant peaks. CHARACTER 1 — KHABIB: Light brown skin, sharp Central Asian features, powerful stocky muscular build. Black Papakha hat, black compression shorts, black MMA gloves, bare feet, no shirt. CHARACTER 2 — BEAR: Massive brown bear, easily twice Khabib's size, powerful and aggressive. AUDIO: Dramatic orchestral music with Dagestani percussion from frame one, building with every exchange, near silence during the tap. Heavy impacts always audible. [0:00-0:02] Khabib and bear facing each other. Bear on hind legs roaring. Khabib in wrestling stance completely expressionless. Close up of his cold eyes. Close up of bear's roaring face. Wide shot showing size difference. Both about to explode. [0:02-0:05] Both charge — Khabib shoots low — bear swipes — Khabib ducks under — drives into bear — bear throws him sideways — Khabib rolls, immediately back on his feet. Fast and brutal. [0:05-0:08] Khabib charges again — slips the swipe — perfect double leg — drives forward — bear crashes to the ground, rocks and dust exploding everywhere. [0:08-0:11] Bear scrambling — Khabib riding on top — bear flips face to face swiping wildly — Khabib slipping every swipe — advances to full mount — bear completely pinned. [0:11-0:13] Bear's paw taps the ground three times. Khabib immediately releases and stands up. Not even breathing hard. [0:13-0:15] Bear looks up at him. Khabib looks down. Nods once. Wide shot of vast Dagestan mountains behind them. Bear stays down. Cinematic cel-shaded 3D anime, semi-realistic CGI, hand-painted textures, Unreal Engine quality, dramatic overcast mountain lighting, digital painting feel, hard-edge brushwork, heavy shadows, not cartoon not Disney not Pixar, film grain, premium anime quality.
输出视频
原图
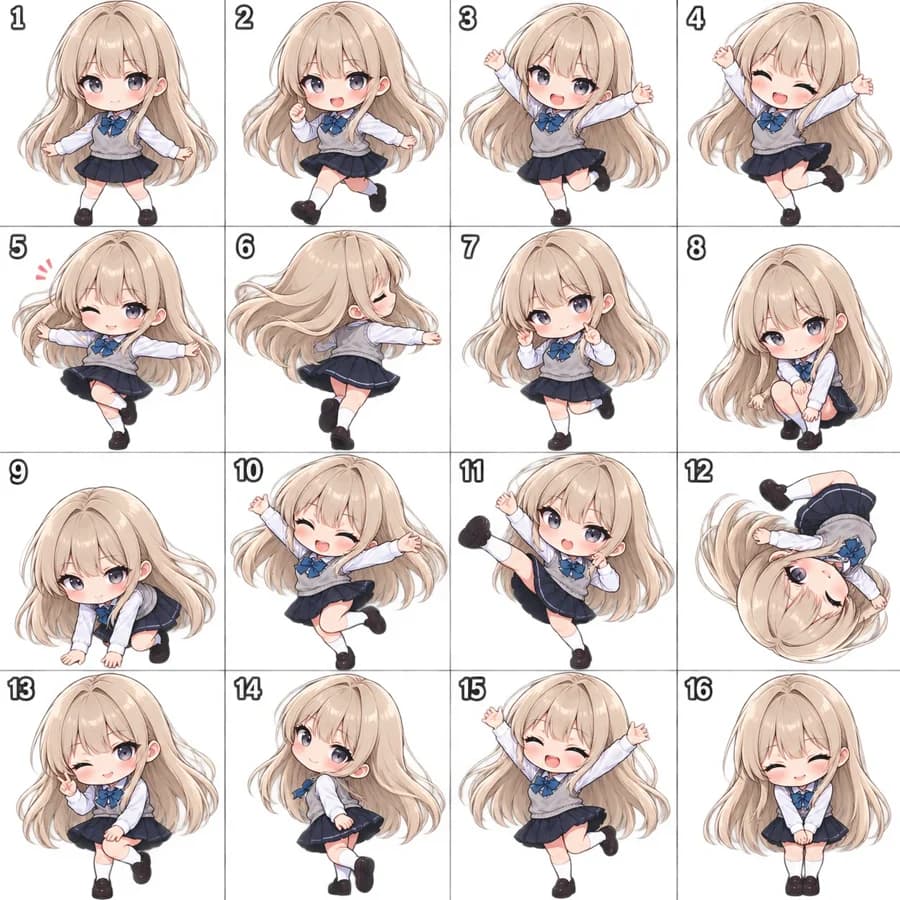
提示词
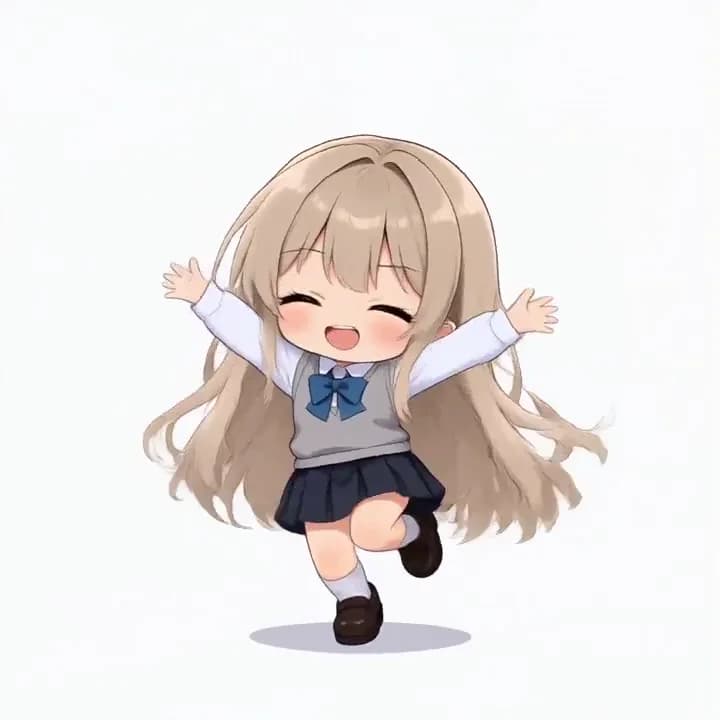
参照したスプライトシート画像を、動きの正確な参考として使用してください。 このちびキャラクターを、スプライトシートの番号順どおりに、1→2→3→4→5→6→7→8→9→10→11→12→13→14→15→16 の順番で厳密に動かしてください。 重要な条件: ・各番号のポーズをキーポーズとして扱う ・1から16まで、順番どおりに動かす ・勝手に別のダンスや振り付けを作らない ・順番を入れ替えない ・コマを飛ばさない ・スプライトシートのポーズの流れをできるだけ忠実に再現する ・ポーズとポーズの間は自然になめらかにつなぐ ・動画の途中でキャラクターデザインを変えない キャラクター条件: ・スプライトシートに描かれている同じちびキャラクターを使う ・髪型、髪色、顔、服装、体型、配色を一貫して維持する 動きの方向性: ・かわいく、弾むようなダンス ・ゲームのスプライトがそのまま動き出したようなイメージ ・元気で明るく、見やすい動き ・可能ならループしやすい自然な流れにする カメラ・構図: ・カメラは固定 ・ズームしない ・カメラ移動しない ・場面転換しない ・全身が常に見えるようにする ・キャラクターは常に中央付近に配置する 背景: ・白背景 ・シンプルで何もない背景 ・小物や背景演出は不要 見た目: ・かわいいアニメ調 ・ちびキャラ比率 ・なめらかな動き ・スプライトシートの見た目をしっかり維持する ・キャラクターは1人だけ 追加条件: ・キャラクターを増やさない ・服装を変えない ・手や足を崩さない ・体を歪ませない ・キャラが見切れないようにする ・別の振り付けにしない 最終的に、スプライトシートの16コマをそのまま動画化したような、自然でかわいいダンス動画にしてください。
输出视频
原图
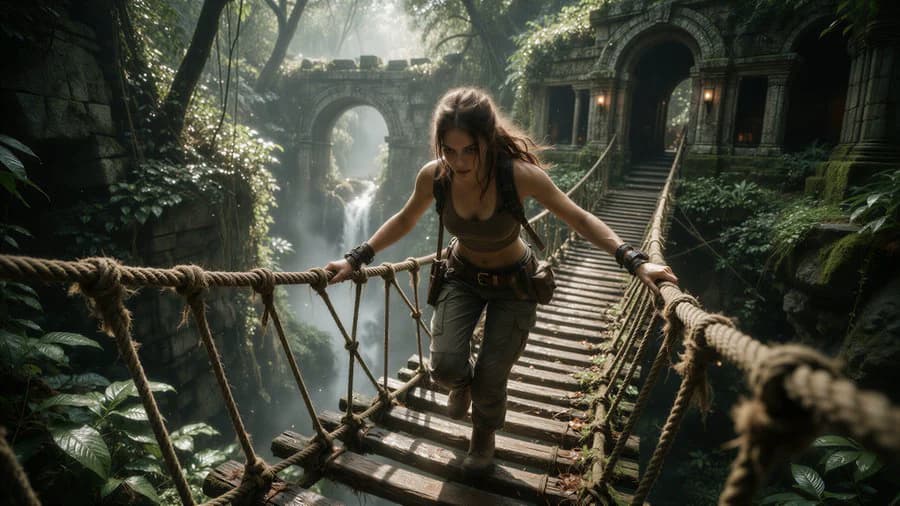
提示词
For the target video, at 0.00 seconds into the target video, <Picture 1> (from [Shot 1]) is fully referenced. integrated_multimodal_description: [Shot 1] A 15-second, 16:9, cinematic photoreal adventure-thriller image-to-video sequence locked to the same exterior ruin space shown in <Picture 1>: the jungle cliff suspension bridge, wet stone ruins at the cliff edge, broken rock lip, and the river gorge hundreds of meters below. Preserve the exact same adult female explorer throughout: same face, bone structure, hairstyle, skin tone, clothing, body type, age impression, and humid sweat texture. Only one character is allowed. No other people, no monsters, no new scene, no interior cut, no mirrored duplicate, no extra limbs. The critical location-state chain is locked: from 00:00 to 00:03.6 she is still on the bridge deck moving forward; at 00:03.6 the bridge breaks and she falls and catches the side rope; from 00:03.6 to 00:12.0 she remains suspended in open air beside the cliff with no stable foothold and never returns to the bridge or cliff edge; only from 00:12.0 to 00:15.0 does she catch the broken lip and climb up for the first and only time. [Shot 2] At 00:00-00:01.8, begin on the bridge deck in a low intimate near shot. Start on her hand crushing the thick rope, then lift into her forward-leaning shoulder-and-back effort. She is still on the bridge deck, moving carefully forward. Her right hand presses the rope, her left steadies it, her left foot tests forward, knees slightly bent, abdomen tight to stabilize the bridge. Her first emotional layer is focused bridge control with panic suppressed: brows lightly drawn together, eyes fixed on the next foothold, lids tense, nostrils opened by restrained breath, lips slightly parted, jaw locked. She says quietly, [English] Easy... keep moving. Filtered jungle daylight shapes wet hair edges, collarbone, and shoulder line. [Shot 3] At 00:01.8-00:03.6, she is still on the bridge deck in a frontal retreating medium shot, moving along the bridge axis toward camera. She accelerates by two quick steps. The wood planks start loosening under her and the bridge suddenly sags. She does not stop; she instantly drops her center of gravity and keeps moving. Her second emotional layer is tightening alertness: brows contract more, gaze narrows sharply, eyes flick between the planks below and the broken lip ahead, nostrils open wider, lips flatten, jaw hardens. Tiny wood splinters and droplets fall through the plank gaps, coarse rope fibers begin fraying, and the bridge shivers with elastic vibration. [Shot 4] At 00:03.6-00:05.4, the bridge breaks. Begin on a tight structural view of planks and rope, then follow the fall briefly. The planks snap apart, the main rope fibers burst one after another, and the bridge section folds and drops. She falls with it and instinctively grabs a side rope with both hands; the rope catches her violently in midair. Make it unmistakable that from this moment she is hanging outside the cliff in open air with both feet off the ground and no bridge support beneath her. Her third emotional layer is uncontrolled terror forced into survival: pupils contract hard, eyes open wide but not caricature-wide, brow center drives down, nostrils strain, teeth clamp, throat loses a breath on the sudden stop. She says, [English] No— hold... hold it! Hard physics must read: rope fibers snap with different thicknesses and recoil, broken planks and wet wood dust tumble downward, her palms scrape the rope and shed fibers, hair lifts with fall inertia then drops back heavy against face and neck. [Shot 5] At 00:05.4-00:07.9, she remains hanging in open air beside the cliff. The camera looks slightly downward along the rope from near her shoulder and forearm, but the frame must always retain her hands, rope, and part of her arm or torso. Below is a narrow gorge river hundreds of meters down, white rapids punching through dark green rock walls, the falling wood immediately swallowed by the current, spray breaking into fine droplets, and cold mist lifting upward. She lets her eyes drop once toward the void, then immediately drags her head and gaze back toward the broken cliff lip. Her fourth emotional layer is fear seen for a flash and then forcibly contained: eyelids tremble, the eyeballs drop for one instant, lips shake slightly, the inhale catches, then focus re-forms. She says, [English] Don't look down... come on. Wind rises from below and lightly shakes damp strands near her temples. [Shot 6] At 00:07.9-00:12.0, she is still hanging in midair with no successful support on the cliff yet. Use a lateral medium close shot at side level, moving with her and the rope as they swing. She turns her body into a pendulum using abdomen, shoulders, knees, and hips to drive herself toward the broken lip. On the first swing she only brushes the broken wood with her fingertips, then immediately swings back out into open air again, still fully hanging on the rope. She instantly changes grip, tightens her core, bends her knees, rolls a shoulder, and loads a second swing. Her fifth emotional layer is pain and refusal to give up: after the first failure the brow drops lower, eye corners tighten, nostrils pulse, lips press and release, one mouth corner twitches with pain; before the second effort her gaze locks hard on the broken lip again. She says, [English] One more... come on, move. The rope forms a real loaded arc and rebounds, the palms show small blood streaks and wet abrasion, the broken wood sheds more fragments where she strikes it. [Shot 7] At 00:12.0-00:15.0, this is the first and only moment she truly leaves the hanging state. Let the camera push in slightly with her upward drive. On the final swing she reaches the highest point, slams a forearm over the broken edge, and only now her knee successfully hooks the remaining wood for the first time. Her left hand claws the edge, the abdomen contracts violently, and she drags her full body up against the cliff, rolls half her torso back over the lip, and finally collapses onto the edge, breathing hard. Her sixth emotional layer is shock after survival and near-collapse: the brows have not fully relaxed, the eyes first pin to the ground and edge, then begin to lose focus half a beat later; nostrils keep flaring fast; the lip line trembles from oxygen debt and pain; the jaw unlocks little by little. No new dialogue. End without cutting to black, holding on her collapsed position at the broken lip, chest heaving, wet hair hanging down, and the blurred white gorge water still surging behind. overall_soundscape: Continuous environmental bed: humid jungle air, distant insects softened by height, rope strain, bridge wood creaks, and the deep constant roar of the gorge river below. Emphasize close breath, hand pressure on wet rope, boots on damp planks, faint cloth drag. Build through plank groans, knot friction, splinters and droplets falling, rope fibers fraying, the bridge rupture, body catch on the side rope, palm scrape against coarse fiber, wind from the gorge, whitewater impact below, pendulum swings, rope tension rise and release, the final impact of forearm and knee on the edge, fingernails scraping wood, more debris falling, and harsh recovery breathing. No bombastic score, no trailer hits, no extra voices. non_diegetic_music: Keep music minimal and subordinate to the physical environment. If any score is used, make it a restrained low-frequency tension bed that thickens during the hanging section and eases slightly into a shocked, breathless aftermath once she collapses onto the edge. No heroic swell, no horror blast, no melodramatic climax.
输出视频
图生视频,出片就带声音
用 MiniMax H3 让静态图动起来,音频会在同一次生成里一起写好——空间底噪、脚步声、一句台词、踩在剪辑点上的配乐。画面和声音同时到达、已经对齐,所以片子拿到手就能直接发,而不是还得再剪。
怎么用 AI 把一张图变成视频
把想让它动起来的图片丢进来。想自己掌控片子怎么开头、怎么收尾?设一张首帧和一张尾帧,中间的运动由 MaxH3 补上。
模型选择器默认打开的是 MiniMax H3,它会连画面带声音一起生成。想要更长的镜头,就换 Wan 3.0 或 Seedance 2.5;想换一种运动的演绎,就试 Veo 3.1 或 Kling——同一张图,同一份积分余额,不用重新上传。
点生成。你的静态图开始动起来,渲染跑完,成片就可以下载了。
准备好让你的图片活过来了吗?
常见问题
那张照片值得动起来
挑一张图,接下来交给 MaxH3。